


DevOps teams rarely suffer from a lack of metrics. They suffer from too many of them. Dashboards are filled with deployment counts, build durations, pipeline success rates, incident totals, infrastructure utilization, and ticket volumes, yet leadership can still struggle to answer a basic question: Is software delivery actually getting better?
That is where DORA metrics remain useful. Their value is not in putting four numbers on a dashboard. The value is in using delivery metrics to understand how effectively an organization turns engineering effort into reliable software. In 2026, that distinction matters even more as AI-assisted development, platform engineering, automated testing, and increasingly autonomous DevOps workflows increase the speed and volume of software changes.
The goal should not be to maximize deployments. It should be to improve the system that turns code changes into reliable production outcomes.
DORA Metrics Are Not a Developer Scorecard
One of the easiest ways to misuse DORA metrics is to turn them into individual performance targets. If engineers are told to increase deployment frequency, they may split changes simply to improve the number. If teams are pressured to reduce lead time, they may optimize the measurement instead of the delivery process. If change failure rate becomes a rigid target, teams may redefine what counts as a failure rather than improving reliability.
DORA metrics work best as system-level engineering signals. They should help leaders identify bottlenecks in software delivery, not rank developers against one another.
The Four Core DORA Metrics
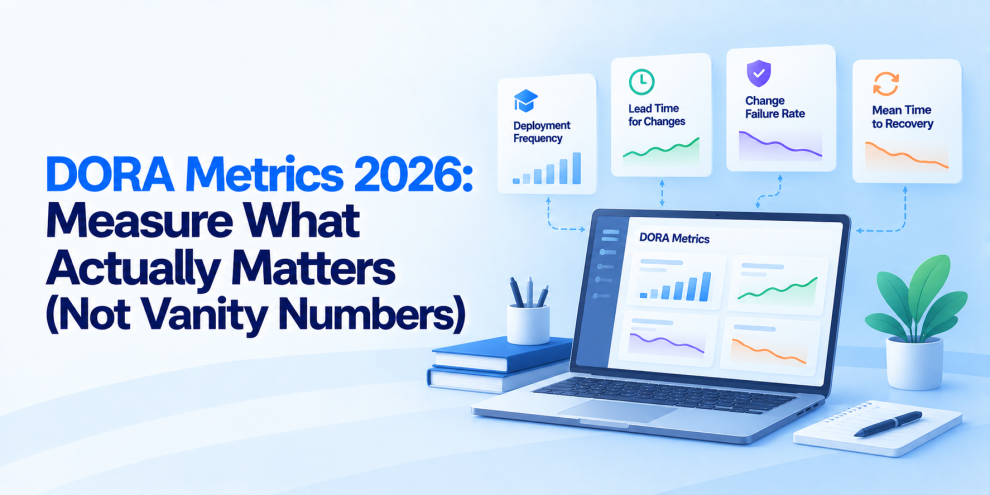
The traditional DORA framework focuses on four core measures: deployment frequency, lead time for changes, change failure rate, and time to restore service.
Deployment frequency indicates how often an organization successfully delivers changes to production. Lead time for changes measures how long it takes for a change to move from code committed to production. Change failure rate looks at the proportion of deployments that result in a production failure requiring remediation, rollback, hotfix, or another corrective action. Time to restore service measures how quickly teams recover after a production failure.
The important point is that these metrics should be considered together. A team deploying several times per day is not necessarily performing well if those releases regularly create incidents. Likewise, a team with extremely short lead times may still have serious delivery problems if recovery is slow.
Deployment Frequency Is Not Productivity
Deployment frequency is one of the easiest metrics to turn into a vanity number. A team can increase its deployment count by breaking work into artificial releases without improving customer value or engineering efficiency.
The more useful question is whether the organization can safely deliver valuable changes when they are ready.
A healthy delivery environment makes small, low-risk releases relatively easy. Teams should not need a major coordination exercise to deploy a routine change. Deployment frequency should therefore be analyzed alongside change size, failure rate, release risk, and customer impact.
The metric is useful when it reveals delivery friction. It becomes a vanity number when teams optimize it for its own sake.
Lead Time Reveals Where Delivery Gets Stuck
Lead time can expose bottlenecks that remain invisible in deployment dashboards. A code change might take only a few hours to implement but several days to reach production because it is waiting for code review, security approval, manual testing, environment provisioning, infrastructure availability, or release coordination.
Breaking lead time into stages makes the problem easier to diagnose: coding, review, build, test, approval, deployment.
The objective is not to eliminate every stage. Some controls exist for good reasons. The objective is to understand where unnecessary waiting exists and determine whether automation, better platform capabilities, or process changes can remove it.
If most of the lead time comes from waiting rather than actual engineering work, hiring more developers may not solve the problem. Improving the delivery system might.
Change Failure Rate Protects Against Reckless Speed
Speed without reliability is not DevOps maturity. Change failure rate provides the counterweight.
If deployment frequency increases while production failures also increase, the organization may simply be moving problems downstream. Teams should investigate which changes are causing failures and why.
Failures may originate from application defects, infrastructure configuration, database migrations, dependency changes, feature flags, environment inconsistencies, or insufficient testing. Connecting change failure rate to these categories makes the metric substantially more useful.
A rising failure rate should trigger investigation into the delivery system rather than simply creating pressure to lower the number.
Recovery Time Measures Operational Resilience
When production fails, engineering teams need to restore service quickly. Recovery time provides insight into how resilient the organization is after something goes wrong.
But recovery speed needs context. A simple service restart might restore availability quickly while leaving the underlying problem unresolved. A complex incident involving data integrity may require more time because engineers are deliberately avoiding unsafe remediation.
Teams should therefore distinguish between restoring service and fully resolving the underlying problem where appropriate.
Observability, rollback capabilities, feature flags, runbooks, ownership models, and platform automation can all influence recovery performance.
The Relationship Between Metrics Matters More Than Any Single Number
The most useful DORA analysis looks at relationships.
Suppose deployment frequency rises while lead time falls and change failure rate remains stable. That may indicate genuine delivery improvement.
Suppose deployment frequency rises while change failure rate and recovery time also rise. The organization may be increasing delivery speed at the expense of reliability.
Suppose lead time remains high despite strong CI/CD automation. The bottleneck may exist in approvals, testing, environment provisioning, or organizational coordination rather than the pipeline itself.
Metrics become powerful when they explain these patterns. A dashboard should therefore help leaders ask why the numbers changed, not simply whether a number went up or down.
Platform Engineering Changes the DORA Conversation
Internal developer platforms are increasingly becoming part of the software delivery system. They can provide standardized pipelines, deployment templates, infrastructure provisioning, observability, security controls, service catalogs, and golden paths.
DORA metrics can help determine whether those capabilities actually reduce engineering friction.
If a platform introduces self-service environments but lead time does not improve, the bottleneck may exist somewhere else. If deployment automation increases frequency but change failure rate rises, the platform may need stronger testing or release safeguards.
The platform should therefore be evaluated through outcomes, not the number of features it provides.
AI Changes How DORA Metrics Should Be Interpreted
AI-assisted development creates another measurement challenge. If developers use coding assistants to generate more code, raw deployment volume may increase. But more generated code does not automatically mean more business value.
AI can also accelerate changes that have not been adequately reviewed or tested. DevOps teams should therefore examine whether AI-assisted development is improving the complete delivery system.
Are changes reaching production faster? Are review and testing bottlenecks changing? Has change failure rate moved? Are incident patterns changing? Are developers spending less time on repetitive delivery work? Is operational workload increasing because more changes are being shipped?
The goal is not to measure how much AI-generated code exists. It is to determine whether AI improves software delivery outcomes.
Do Not Optimize DORA Metrics in Isolation
Metrics can create unintended behavior when treated as independent targets. Reducing lead time at any cost could encourage risky deployments. Increasing deployment frequency could encourage unnecessary releases. Reducing recovery time could encourage superficial remediation. Lowering reported failure rates could encourage teams to redefine what counts as a failure.
DORA metrics should therefore sit inside a broader engineering measurement system. They should be interpreted alongside reliability, security, customer experience, developer experience, cost, and business outcomes.
Add Reliability and Customer Metrics
A delivery system exists to produce reliable software for users. DORA metrics should therefore be connected to service-level indicators and customer outcomes.
Useful supporting measurements include availability, latency, error rates, incident severity, customer-impacting incidents, support volume, and service-level objective performance.
This creates a more complete picture. A team may improve delivery speed without improving the customer experience. Conversely, a temporary slowdown in deployments may be justified if the organization is handling a major reliability problem.
Engineering leaders need enough context to distinguish between those situations.
Measure Developer Experience Without Creating Another Vanity Dashboard
Developer experience is closely connected to delivery performance. Engineers lose time waiting for builds, debugging CI failures, requesting environments, resolving deployment problems, navigating unclear ownership, and dealing with inconsistent infrastructure.
Useful signals include CI queue time, build failure frequency, environment provisioning time, deployment troubleshooting time, infrastructure request turnaround, and recurring platform support issues.
The purpose of measuring these signals is to identify friction, not create another developer leaderboard.
DORA Metrics Need Consistent Definitions
Metrics become difficult to compare when different teams calculate them differently. One team may define a deployment as any production change, while another counts only customer-facing releases. One team may classify a rollback as a failed deployment, while another treats it as a separate operational event.
Organizations should establish clear definitions and document how metrics are calculated. Consistency matters more than creating an overly complicated measurement system.
Teams should also be careful when comparing metrics across different services. A low-risk internal service and a highly regulated financial platform may have very different release characteristics.
Stop Turning Metrics Into Targets
A useful principle is: Measure the system. Do not weaponize the measurement.
When metrics become performance targets, people naturally adapt their behavior to the metric. Instead, leadership should use DORA data to identify constraints and investment opportunities.
If lead time is high, investigate the waiting stages. If change failure rate is increasing, identify the dominant failure patterns. If recovery time is poor, examine observability, ownership, rollback mechanisms, and incident response. If deployment frequency is low, determine whether the problem is technical, organizational, or product-related.
The metric should lead to a question. The question should lead to an engineering improvement.
Build a Practical DevOps Scorecard
A useful engineering scorecard can combine DORA metrics with supporting signals across several dimensions.
Delivery: deployment frequency and lead time.
Reliability: change failure rate, recovery time, availability, and SLO performance.
Developer experience: CI wait time, environment provisioning time, deployment friction, and platform support volume.
Security: vulnerable releases, remediation time, policy violations, and security control coverage.
Cost: CI/CD infrastructure cost, cloud utilization, and cost per deployment or workload where meaningful.
Customer impact: customer-facing incidents, latency, error rates, and service-level performance.
This provides enough context to understand whether delivery improvements are actually healthy without turning the engineering organization into a collection of competing metrics.
What Engineering Leaders Should Ask
Technology leaders should periodically ask: Are our DORA metrics improving because engineering is becoming more effective, or because teams are optimizing the measurements? Where does most lead time actually accumulate? Are faster deployments increasing production risk? Which changes most frequently cause incidents? How quickly can teams safely restore service? Are platform investments reducing delivery friction? Has AI-assisted development changed our failure patterns? Are DORA improvements translating into better customer outcomes? Do different teams calculate metrics consistently? Can engineers use the data to identify specific improvements?
These questions turn metrics into an engineering management tool rather than a reporting exercise.
Where Engineering Partners Fit
Improving DevOps performance requires more than installing dashboards. It involves CI/CD architecture, platform engineering, cloud infrastructure, observability, security automation, developer experience, and reliable application delivery. Engineering organizations such as GeekyAnts work across these areas to help teams improve delivery systems while keeping reliability and operational controls in view.
The goal should not be to produce better-looking DevOps dashboards. It should be to build a delivery system where engineers can ship useful changes quickly, recover safely, and understand where friction exists.
DORA in 2026: Measure Outcomes, Not Activity
The biggest mistake organizations can make with DORA metrics is treating them as a scoreboard.
A deployment count cannot tell you whether customers received more value. A shorter lead time cannot tell you whether the release was safe. A lower failure rate cannot tell you whether teams are accurately reporting incidents. A faster recovery time cannot tell you whether the underlying problem was actually fixed.
The real value of DORA metrics comes from combining them. When deployment frequency, lead time, change failure rate, and recovery performance are viewed together, they provide a useful picture of how software delivery is functioning.
In 2026, that context is becoming even more important as AI and platform engineering accelerate the volume of software changes.
The best DevOps organizations will not be the ones with the most impressive dashboard. They will be the ones that can answer a more important question:
Are we becoming better at delivering reliable software, or are we simply getting better at measuring ourselves?
For more, visit our homepage!


Add Comment